Multimodal references
Combines prompts with images, video clips, audio, and frame references.

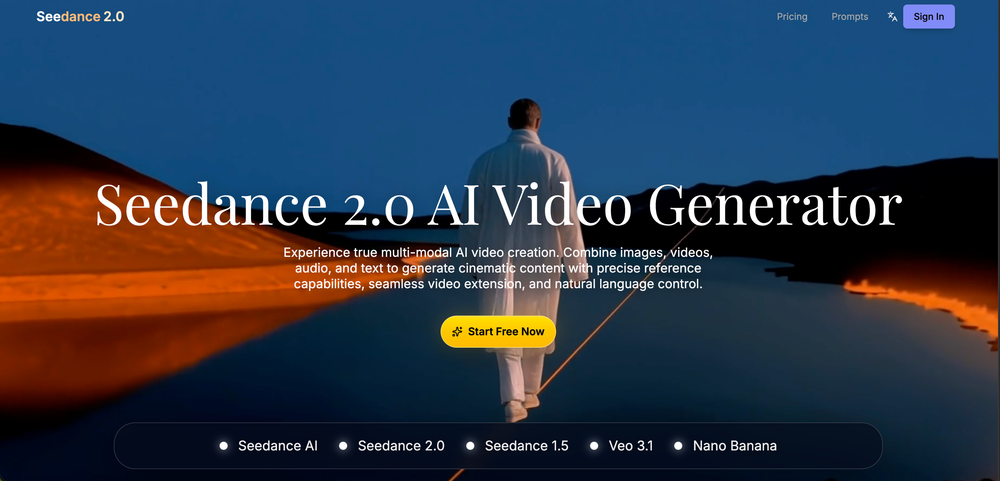
A multimodal AI video platform combining text, images, video, and audio for cinematic generation and extension.

专业的DDSM批量二维码生成工具,在线快速生成多个高质量二维码,支持自定义样式、格式导出与打包下载。
Combines prompts with images, video clips, audio, and frame references.
Guides how a generated clip begins, ends, and extends a scene.
Uses detailed written direction for movement, framing, and cinematic intent.
Creates up to several variations from the same prompt and settings.
Supports extending a scene when a short clip needs additional duration.
Test scenes, transitions, and camera direction before production.
Create visual alternatives for ads, launches, and social storytelling.
Animate a still, clip, or other approved reference with controlled motion.
Generate multiple takes and select the strongest direction for editing.
Seedance 2.5 is a multimodal AI video generation workspace designed to combine text, images, video, and audio into cinematic outputs. Its workflow highlights precise reference capabilities, first and last frames, camera direction, natural-language control, and seamless video extension.
Creators can generate several variations from the same brief and compare them before selecting a direction. Confirm provider policies around copyrighted characters, logos, music, sensitive content, and commercial use.